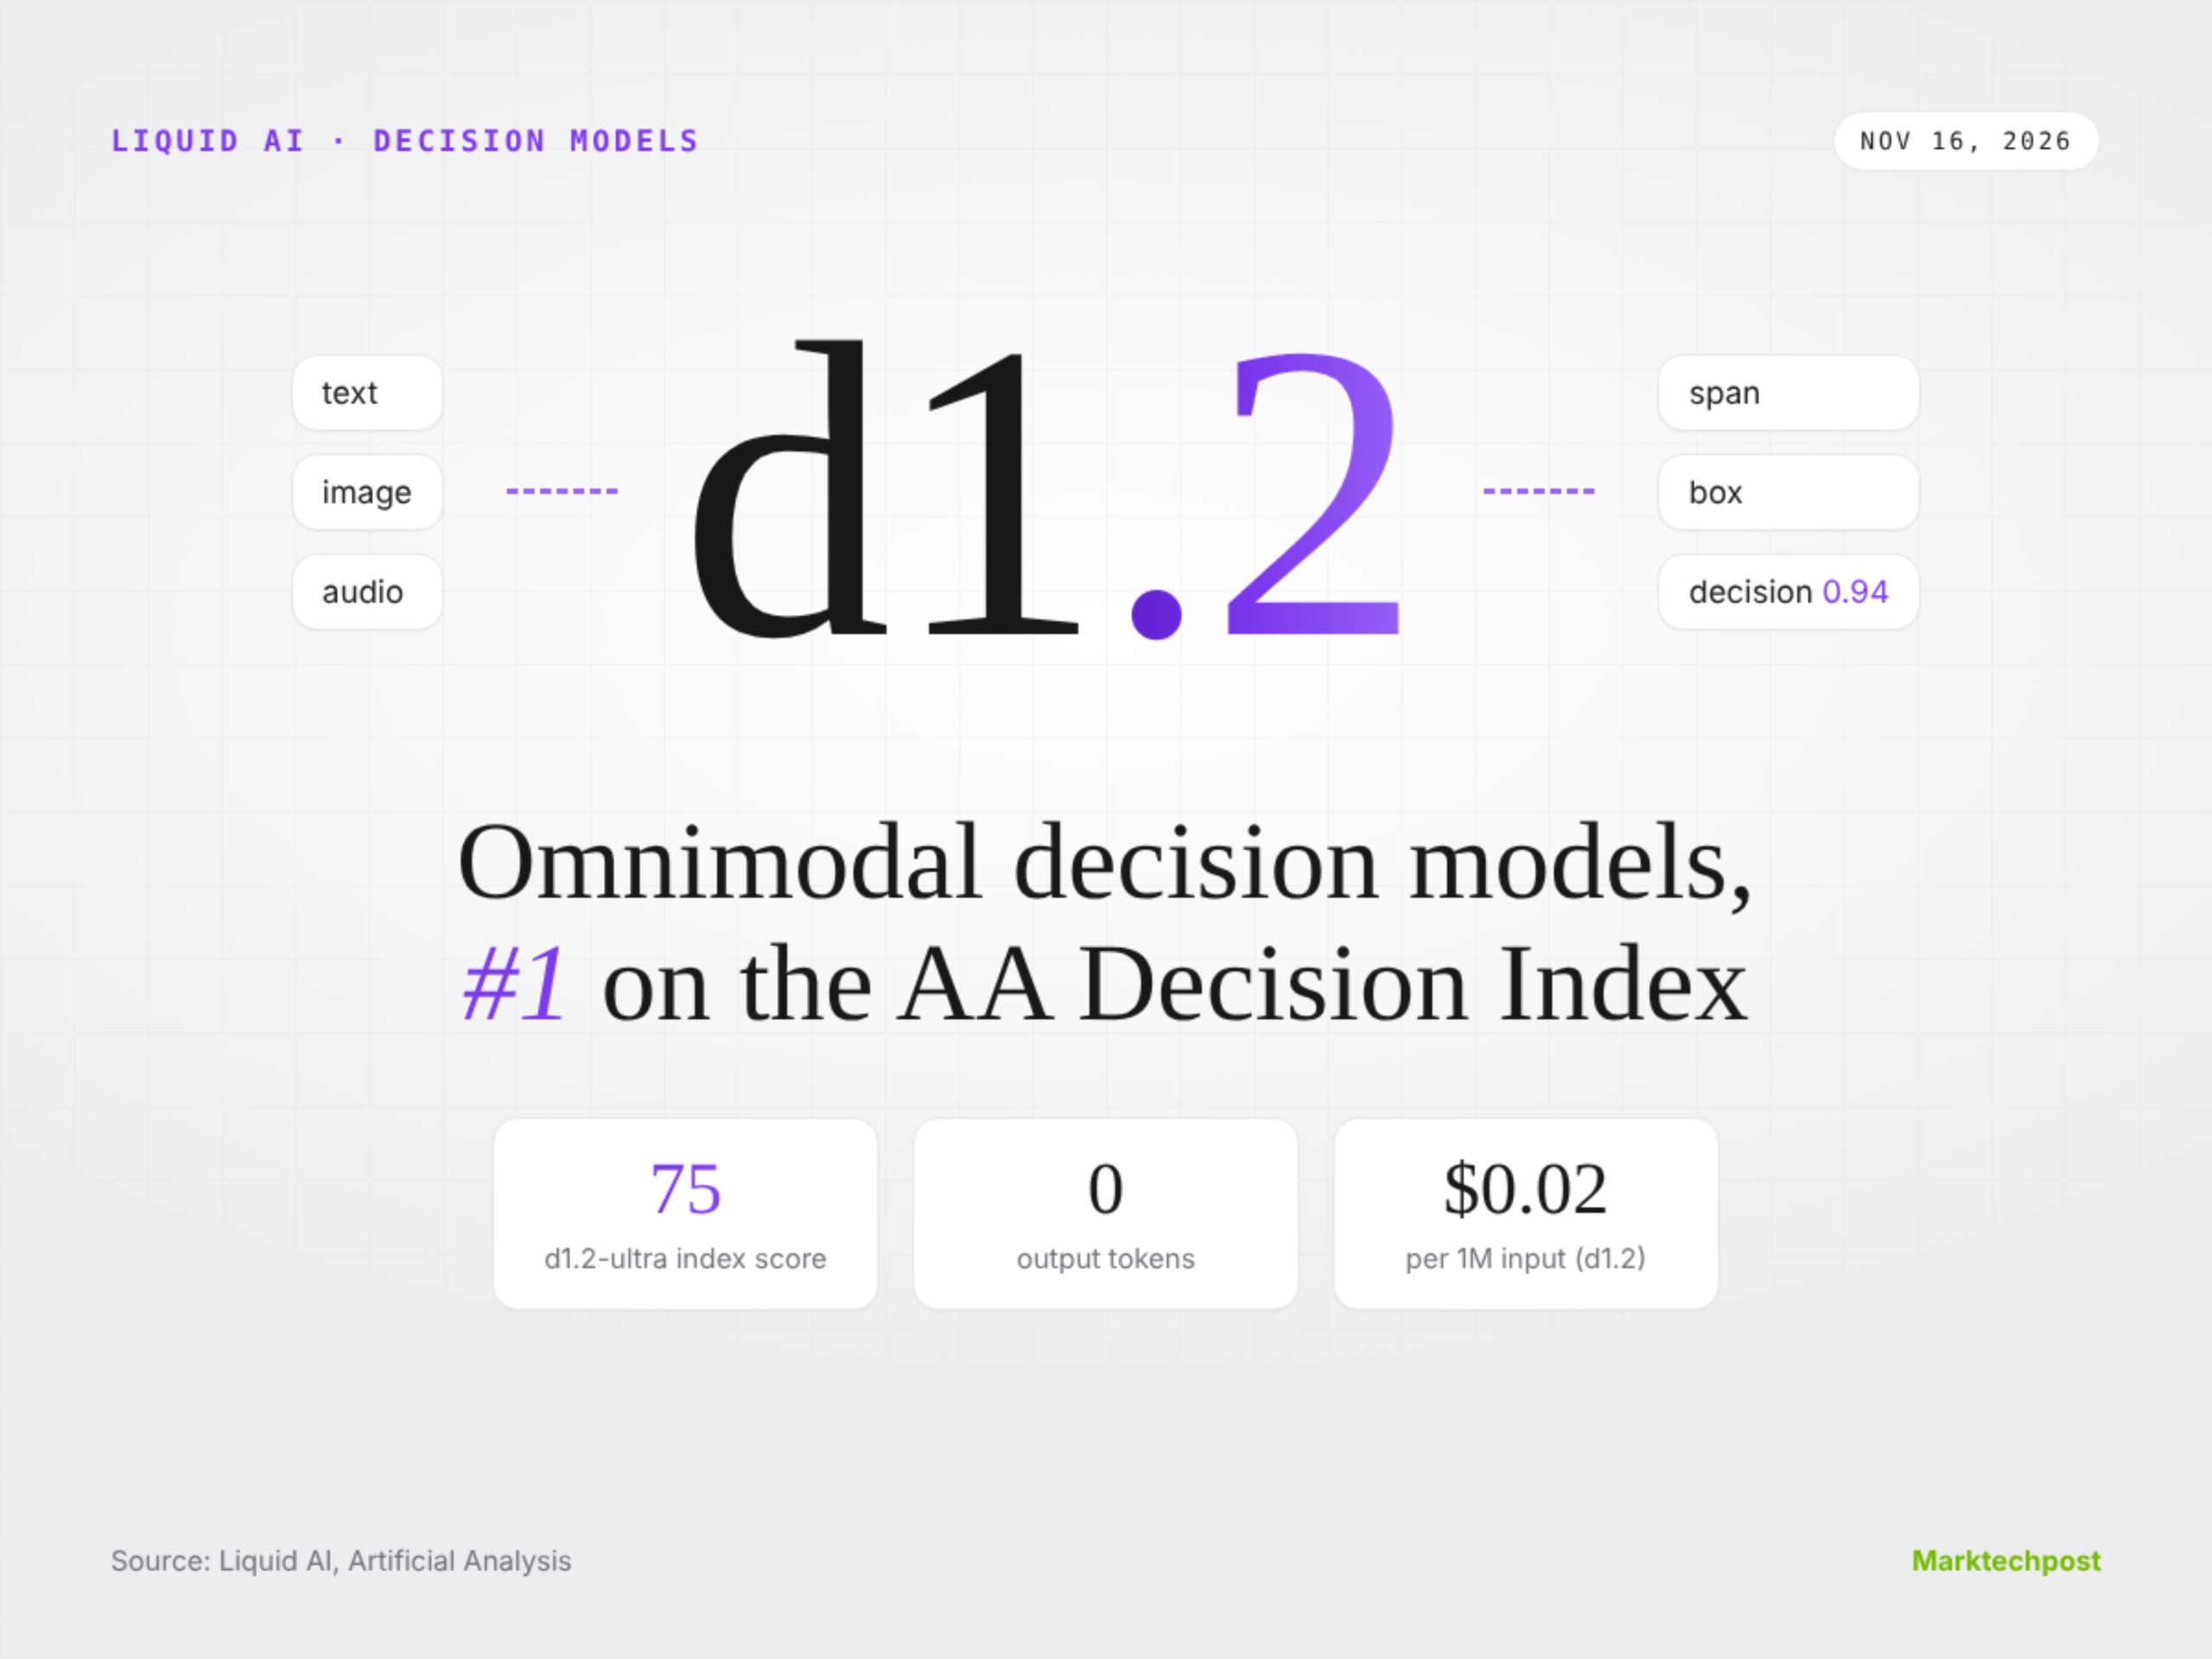
Liquid AI just released d1.2 and d1.2-ultra. A decision model does not write text. It returns calibrated probabilities over a fixed set of answers. The Liquid AI d1.2 decision model family now accepts text, images and audio. It also adds 5 new answer types. d1.2-ultra scores 75 on the Artificial Analysis Decision Index v2.1, the top score among decision models on the index. You can check the deployment options and specs here through our GPULeaderboard.com chrome extension.
TL;DR
- Size: Parameters not disclosed. Up to 65,536 input tokens per question, 128 questions per call.
- Runs on: Hosted Liquid API only. No weights yet; Liquid AI says it will open them “at some point”.
- Performance: d1.2-ultra 75 and d1.2 69 on the AA Decision Index v2.1.
- Best: 0.8-point calibration error for d1.2-ultra across 13 benchmarks (Liquid AI test).
What is Liquid AI d1.2?
d1.2 is a hosted decision model from Liquid AI that answers typed questions about text, images or audio in 1 call. It returns a probability per option and generates zero output tokens, so only input is billed.
d1.2-ultra targets harder decisions. d1.2 is faster and costs less than half as much. The model IDs are d1.2 (default) and d1.2-ultra. Earlier d1, d1.1 and d1-ultra are now deprecated and do not support audio or the new tasks.
What are the 5 new tasks in d1.2?
d1.2 adds 5 typed answers on the same endpoint and request format:
- Read a value (
text,number,date): returns the value plus the characters it came from. It answers “not found” instead of guessing. - Find every span (
spans): returns each matching passage, such as names or emails, with its position. - Locate objects (
box,boxes): returns 1 rectangle, or 1 per instance with a count. - Estimate a number (
numberwithrange): returns a best guess and a range, for example 12 within 10 to 14. - Pick every option that applies (
choicewithmultiple): returns each matching label with its own probability.
How does audio input work?
Audio can be the subject of a question, such as which language is spoken or whether a siren is audible. The question can also be spoken. The API takes 16-bit PCM WAV and counts 10 tokens per second of audio. On held-out ESC-50 and FLEURS (43 languages) recordings, both models answer 95% to 97% of questions correctly.
How does d1.2 score on the Artificial Analysis Decision Index?
The index combines 6 evaluations. AA-Paperclip carries 30% of the weight. EvalSafe-O*NET-AA, AA-Omniscience-Decision v1.1, HLE-MultiChoice v1.1 and AA-Symmetry v1.1 carry 15% each. When2Call carries 10%. Its Decision Score penalizes confident wrong answers.
On the AA chart shared by Liquid AI, d1.2-ultra scores 75. Drex Max v1.1, SubQ Snap 1.2 and GLiDE v1.2 follow at 73. d1.2 scores 69. That is 2 points below the deprecated d1-ultra at 71. Liquid AI argues no model scores higher than d1.2 for less money.
How well calibrated are the probabilities?
A calibrated model that says 80% is right about 80% of the time, so teams can route low-confidence cases to humans. Across 13 benchmarks and 22,505 questions, Liquid AI reports these calibration errors:
- d1.2-ultra: 0.8 points
- d1.2: 1.2
- Jev 1.14: 2.7
- Perplexity Decider v1.3: 3.7
- GPT-6 Luna (Decisions API): 7.2
Note: These figures come from Liquid AI’s own test.
How accurate are the new tasks?
Liquid AI used held-out splits of public datasets; no public benchmark exists yet.
| Task (dataset) | d1.2-ultra | d1.2 |
|---|---|---|
| Read a value from receipts (CORD, SROIE) | 98% | 96% |
| Find personal data, precision / recall (Nemotron PII) | 94% / 93% | 92% / 88% |
| Locate an object (RefCOCO, RefCOCO+, RefCOCOg) | 94% | 94% |
| Count objects within 1 (COCO) | 93% | 92% |
| Pick every object present (COCO) | 87% | 90% |
d1.2 beats d1.2-ultra on multi-label picks, 90% to 87%.
d1.2 vs other decision models
| Metrics | d1.2-ultra | d1.2 | Drex Max v1.1 (Nace.AI) | Decider v1.3 (Perplexity) | Jev 1.14 (TypeSafe) |
|---|---|---|---|---|---|
| AA Decision Index v2.1 | 75 | 69 | 73 | 70 | 66 |
| Calibration error (Liquid test) | 0.8 | 1.2 | Not reported | 3.7 | 2.7 |
| Input price per 1M tokens | $0.042 | $0.02 | $0.03 | $0.02 | $0.042 |
| Output price | $0 | $0 | $0 | $0 | $0 |
| Input limit | 65,536 per question | 65,536 per question | 262,144 | 262,144 | 65.5K |
| Inputs | Text, image, audio | Text, image, audio | Text, image | Text, image | Text |
| Parameters | Not disclosed | Not disclosed | Not disclosed | 27B base (Qwen3.8-27B) | Not disclosed |
| Weights | Planned, no date | Planned, no date | v1.1 not released | Apache 2.0 | Proprietary |
 </button><div class=”stxt” id=”stxt”>Press Next to step through a d1.2 request.</div></div>
<div class=”note”>Limits from Liquid AI’s d1 docs: 65,536 input tokens per question, 4.5 MB request body. Parameter count and architecture are not disclosed.</div>
</div>
<div class=”pane” data-p=”1″>
<div class=”grid5″>
<div class=”tcard on” data-k=”0″><b>Read a value</b><code>text · number · date</code></div>
<div class=”tcard” data-k=”1″><b>Find every span</b><code>spans</code></div>
<div class=”tcard” data-k=”2″><b>Locate objects</b><code>box · boxes</code></div>
<div class=”tcard” data-k=”3″><b>Estimate a number</b><code>number + range</code></div>
<div class=”tcard” data-k=”4″><b>Pick all that apply</b><code>choice + multiple</code></div>
</div>
<div class=”demo”><div><div class=”lbl”>You ask</div><pre id=”dq”></pre></div><div><div class=”lbl”>Shape of the answer (illustrative)</div><pre id=”da”></pre></div></div>
<div class=”acc” id=”dacc”></div>
</div>
<div class=”pane” data-p=”2″>
<div class=”lbl”>Artificial Analysis Decision Index v2.1 (higher is better)</div>
<div class=”bars” id=”dib”></div>
<div class=”note”>Scores from the AA chart shared by Liquid AI on Nov 16, 2026. Selected models shown. Index weights: AA-Paperclip 30%, When2Call 10%, 4 others 15% each.</div>
</div>
<div class=”pane” data-p=”3″>
<div class=”lbl”>Calibration error, points (lower is better)</div>
<div class=”bars” id=”cab”></div>
<div class=”note”>Liquid AI test: 13 benchmarks, 22,505 questions answered by all 5 models. Not an independent evaluation. A well-calibrated model saying 80% is right about 80% of the time, so you can route low-confidence cases to human review.</div>
</div>
<div class=”pane” data-p=”4″>
<div class=”calc”>
<div>
<label>Text state tokens: <b id=”vt”>1,000</b><input type=”range” id=”it” min=”0″ max=”60000″ step=”500″ value=”1000″></label>
<label>1024×1024 images: <b id=”vi”>1</b> <small>(1,536 tokens each)</small><input type=”range” id=”ii” min=”0″ max=”8″ value=”1″></label>
<label>Audio seconds: <b id=”va”>0</b> <small>(10 tokens per second)</small><input type=”range” id=”ia” min=”0″ max=”300″ step=”5″ value=”0″></label>
<label>Questions: <b id=”vq”>3</b> × tokens each: <b id=”vqt”>50</b> <small>(your estimate)</small><input type=”range” id=”iq” min=”1″ max=”128″ value=”3″><input type=”range” id=”iqt” min=”10″ max=”500″ step=”10″ value=”50″></label>
</div>
<div class=”out”>
<div class=”lbl” style=”color:#D4C0FF!important”>Cost per 1M requests</div>
<div class=”row”><span>Tokens per request</span><b id=”tok”>0</b></div>
<div class=”row”><span>d1.2 ($0.02 / 1M)</span><b id=”c1″>$0</b></div>
<div class=”row”><span>d1.2-ultra ($0.042 / 1M)</span><b id=”c2″>$0</b></div>
<div class=”big” style=”margin-top:10px”>d1.2 saves <span id=”sv”>0%</span></div>
<div class=”note” style=”color:#D4C0FF!important”>Output tokens are always 0. State and media are billed once per request; each question adds its own tokens.</div>
</div>
</div>
</div>
<div class=”ft”><span>Sources: <a href=”https://www.liquid.ai/blog/d1-2″ target=”_blank” rel=”noopener”>liquid.ai/blog/d1-2</a> · <a href=”https://docs.liquid.ai/lfm/models/d1″ target=”_blank” rel=”noopener”>docs.liquid.ai</a> · self-reported unless noted</span><b>© Marktechpost</b></div>
<script>
(function(){
var R=document.getElementById(‘mtp-d12x’);
function post(){try{parent.postMessage({mtpH:R.offsetHeight+40,id:’mtp-d12x’},’*’)}catch(e){}}
var tabs=R.querySelectorAll(‘.tab’),panes=R.querySelectorAll(‘.pane’);
tabs.forEach(function(t){t.onclick=function(){tabs.forEach(function(x){x.classList.remove(‘on’)});panes.forEach(function(x){x.classList.remove(‘on’)});t.classList.add(‘on’);var p=R.querySelector(‘[data-p=”‘+t.dataset.t+'”]’);p.classList.add(‘on’);if(t.dataset.t===’2′)bars(‘dib’,DI,80);if(t.dataset.t===’3′)bars(‘cab’,CA,8);setTimeout(post,60)}});
var S=[‘Press Next to step through a d1.2 request.’,’1. You send a state (text, JSON, images or audio) plus typed questions.’,’2. d1.2 reads the state and every question in a single forward pass.’,’3. It returns a probability per option and typed answers. No text is generated.’,’4. You set a threshold: confident answers act automatically, low-confidence ones go to a human.’];
var s=0,core=R.querySelector(‘#core’);
function step(){R.querySelector(‘#stxt’).textContent=S[s];R.querySelectorAll(‘[data-s=”1″]’).forEach(function(c){c.classList.toggle(‘lit’,s>=1)});R.querySelector(‘#a1’).classList.toggle(‘go’,s>=2);R.querySelector(‘#a2’).classList.toggle(‘go’,s>=3);R.querySelectorAll(‘[data-s=”3″]’).forEach(function(c){c.classList.toggle(‘lit’,s>=3)});if(s===2){core.classList.remove(‘pulse’);void core.offsetWidth;core.classList.add(‘pulse’)}}
R.querySelector(‘#next’).onclick=function(){s=s<4?s+1:0;step()};R.querySelector(‘#prev’).onclick=function(){s=s>0?s-1:0;step()};
var T=[
[‘state: invoice.pngnquestion: “How much is due?”ntype: number’,’value: 1234.50nsource: “1 234,50″nfound: 0.99n(if absent: “not found”)’,’Receipts (CORD, SROIE): d1.2-ultra 98%, d1.2 96%’],
[‘state: support note (text)nquestion: “Every piece of personal data”ntype: spans’,’spans:n name [start,end]n phone [start,end]n email [start,end]’,’PII precision / recall (Nemotron PII): d1.2-ultra 94% / 93%, d1.2 92% / 88%’],
[‘state: photo.jpg (exactly 1 image)nquestion: “Every tree”ntype: boxes’,’boxes: [x1,y1,x2,y2] …ncount: nn(box: 1 rectangle or “not found”)’,’Locate an object (RefCOCO family): 94% for both models’],
[‘state: crowd.jpgnquestion: “How many people?”ntype: number + range’,’estimate: 12nrange: 10 to 14′,’Count within 1 (COCO): d1.2-ultra 93%, d1.2 92%’],
[‘state: support messagenquestion: “Which topics apply?”ntype: choice, multiple: true’,’billing: pndelivery: pn(each with its own probability)’,’Pick every object present (COCO): d1.2-ultra 87%, d1.2 90%’]];
var tc=R.querySelectorAll(‘.tcard’);
function demo(k){tc.forEach(function(c){c.classList.toggle(‘on’,c.dataset.k==k)});R.querySelector(‘#dq’).textContent=T[k][0];R.querySelector(‘#da’).textContent=T[k][1];R.querySelector(‘#dacc’).innerHTML='<b>Liquid AI internal test:</b> ‘+T[k][2]}
tc.forEach(function(c){c.onclick=function(){demo(+c.dataset.k)}});demo(0);
var DI=[[‘d1.2-ultra’,75,’me’],[‘Drex Max v1.1’,73],[‘SubQ Snap 1.2’,73],[‘GLiDE v1.2’,73],[‘Decider v1.3’,70],[‘d1.2′,69,’me2’],[‘Jev 1.14’,66],[‘GPT-6 Luna (Decisions)’,60]];
var CA=[[‘d1.2-ultra’,0.8,’me’],[‘d1.2′,1.2,’me2’],[‘Jev 1.14’,2.7],[‘Perplexity Decider v1.3’,3.7],[‘GPT-6 Luna (Decisions API)’,7.2]];
function bars(id,d,mx){var el=R.querySelector(‘#’+id);el.innerHTML=d.map(function(r){return ‘<div class=”bar”><span>’+r[0]+'</span><div class=”track”><div class=”fill ‘+(r[2]||”)+'” data-w=”‘+(r[1]/mx*100)+'”></div></div><span class=”v”>’+r[1]+'</span></div>’}).join(”);setTimeout(function(){el.querySelectorAll(‘.fill’).forEach(function(f){f.style.width=f.dataset.w+’%’})},40)}
function f(n){return n.toLocaleString(‘en-US’)}
function calc(){var t=+R.querySelector(‘#it’).value,i=+R.querySelector(‘#ii’).value,a=+R.querySelector(‘#ia’).value,q=+R.querySelector(‘#iq’).value,qt=+R.querySelector(‘#iqt’).value;
R.querySelector(‘#vt’).textContent=f(t);R.querySelector(‘#vi’).textContent=i;R.querySelector(‘#va’).textContent=a;R.querySelector(‘#vq’).textContent=q;R.querySelector(‘#vqt’).textContent=qt;
var tok=t+i*1536+Math.ceil(a*10)+q*qt;R.querySelector(‘#tok’).textContent=f(tok);
R.querySelector(‘#c1’).textContent=’$’+(tok*0.02).toFixed(2);R.querySelector(‘#c2’).textContent=’$’+(tok*0.042).toFixed(2);R.querySelector(‘#sv’).textContent=Math.round((1-0.02/0.042)*100)+’%’}
R.querySelectorAll(‘input’).forEach(function(x){x.oninput=calc});calc();
window.addEventListener(‘load’,post);window.addEventListener(‘resize’,post);setTimeout(post,300);
})();
</script>
</div>
</body></html>”>
Pricing and deployment
Pricing is $0.02 per 1M input tokens for d1.2 and $0.042 for d1.2-ultra. New organizations get $2 in free credit on Liquid Console.
Images cost 1.5 tokens per 32×32 patch, so a 1024×1024 image is 1,536 tokens. Shared state and media are billed once; each extra question adds only its own tokens.
Request limits per call:
- 128 questions and a 4.5 MB request body
- 8 images, or exactly 1 for
boxandboxes - 8 audio clips and 300 seconds of total audio
The endpoint is https://api.liquid.ai/decisions/v1/systemone.
Key Takeaways
- d1.2-ultra scores 75 on the AA Decision Index v2.1, first among decision models.
- Both models now read text, images and audio with 0 output tokens.
- 5 new answer types: values, spans, boxes, ranged estimates, multi-label choices.
- d1.2-ultra reports 0.8-point calibration error vs 3.7 for Perplexity Decider v1.3.
- Hosted only for now: no weights, parameter counts or latency figures.
Check out the launch blog, the d1 API docs and the AA Decision Index. You can check the deployment options and specs here through our GPULeaderboard.com chrome extension.
Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
The post Liquid AI Releases d1.2 and d1.2-ultra: Omnimodal Decision Models That Top the AA Decision Index appeared first on MarkTechPost.