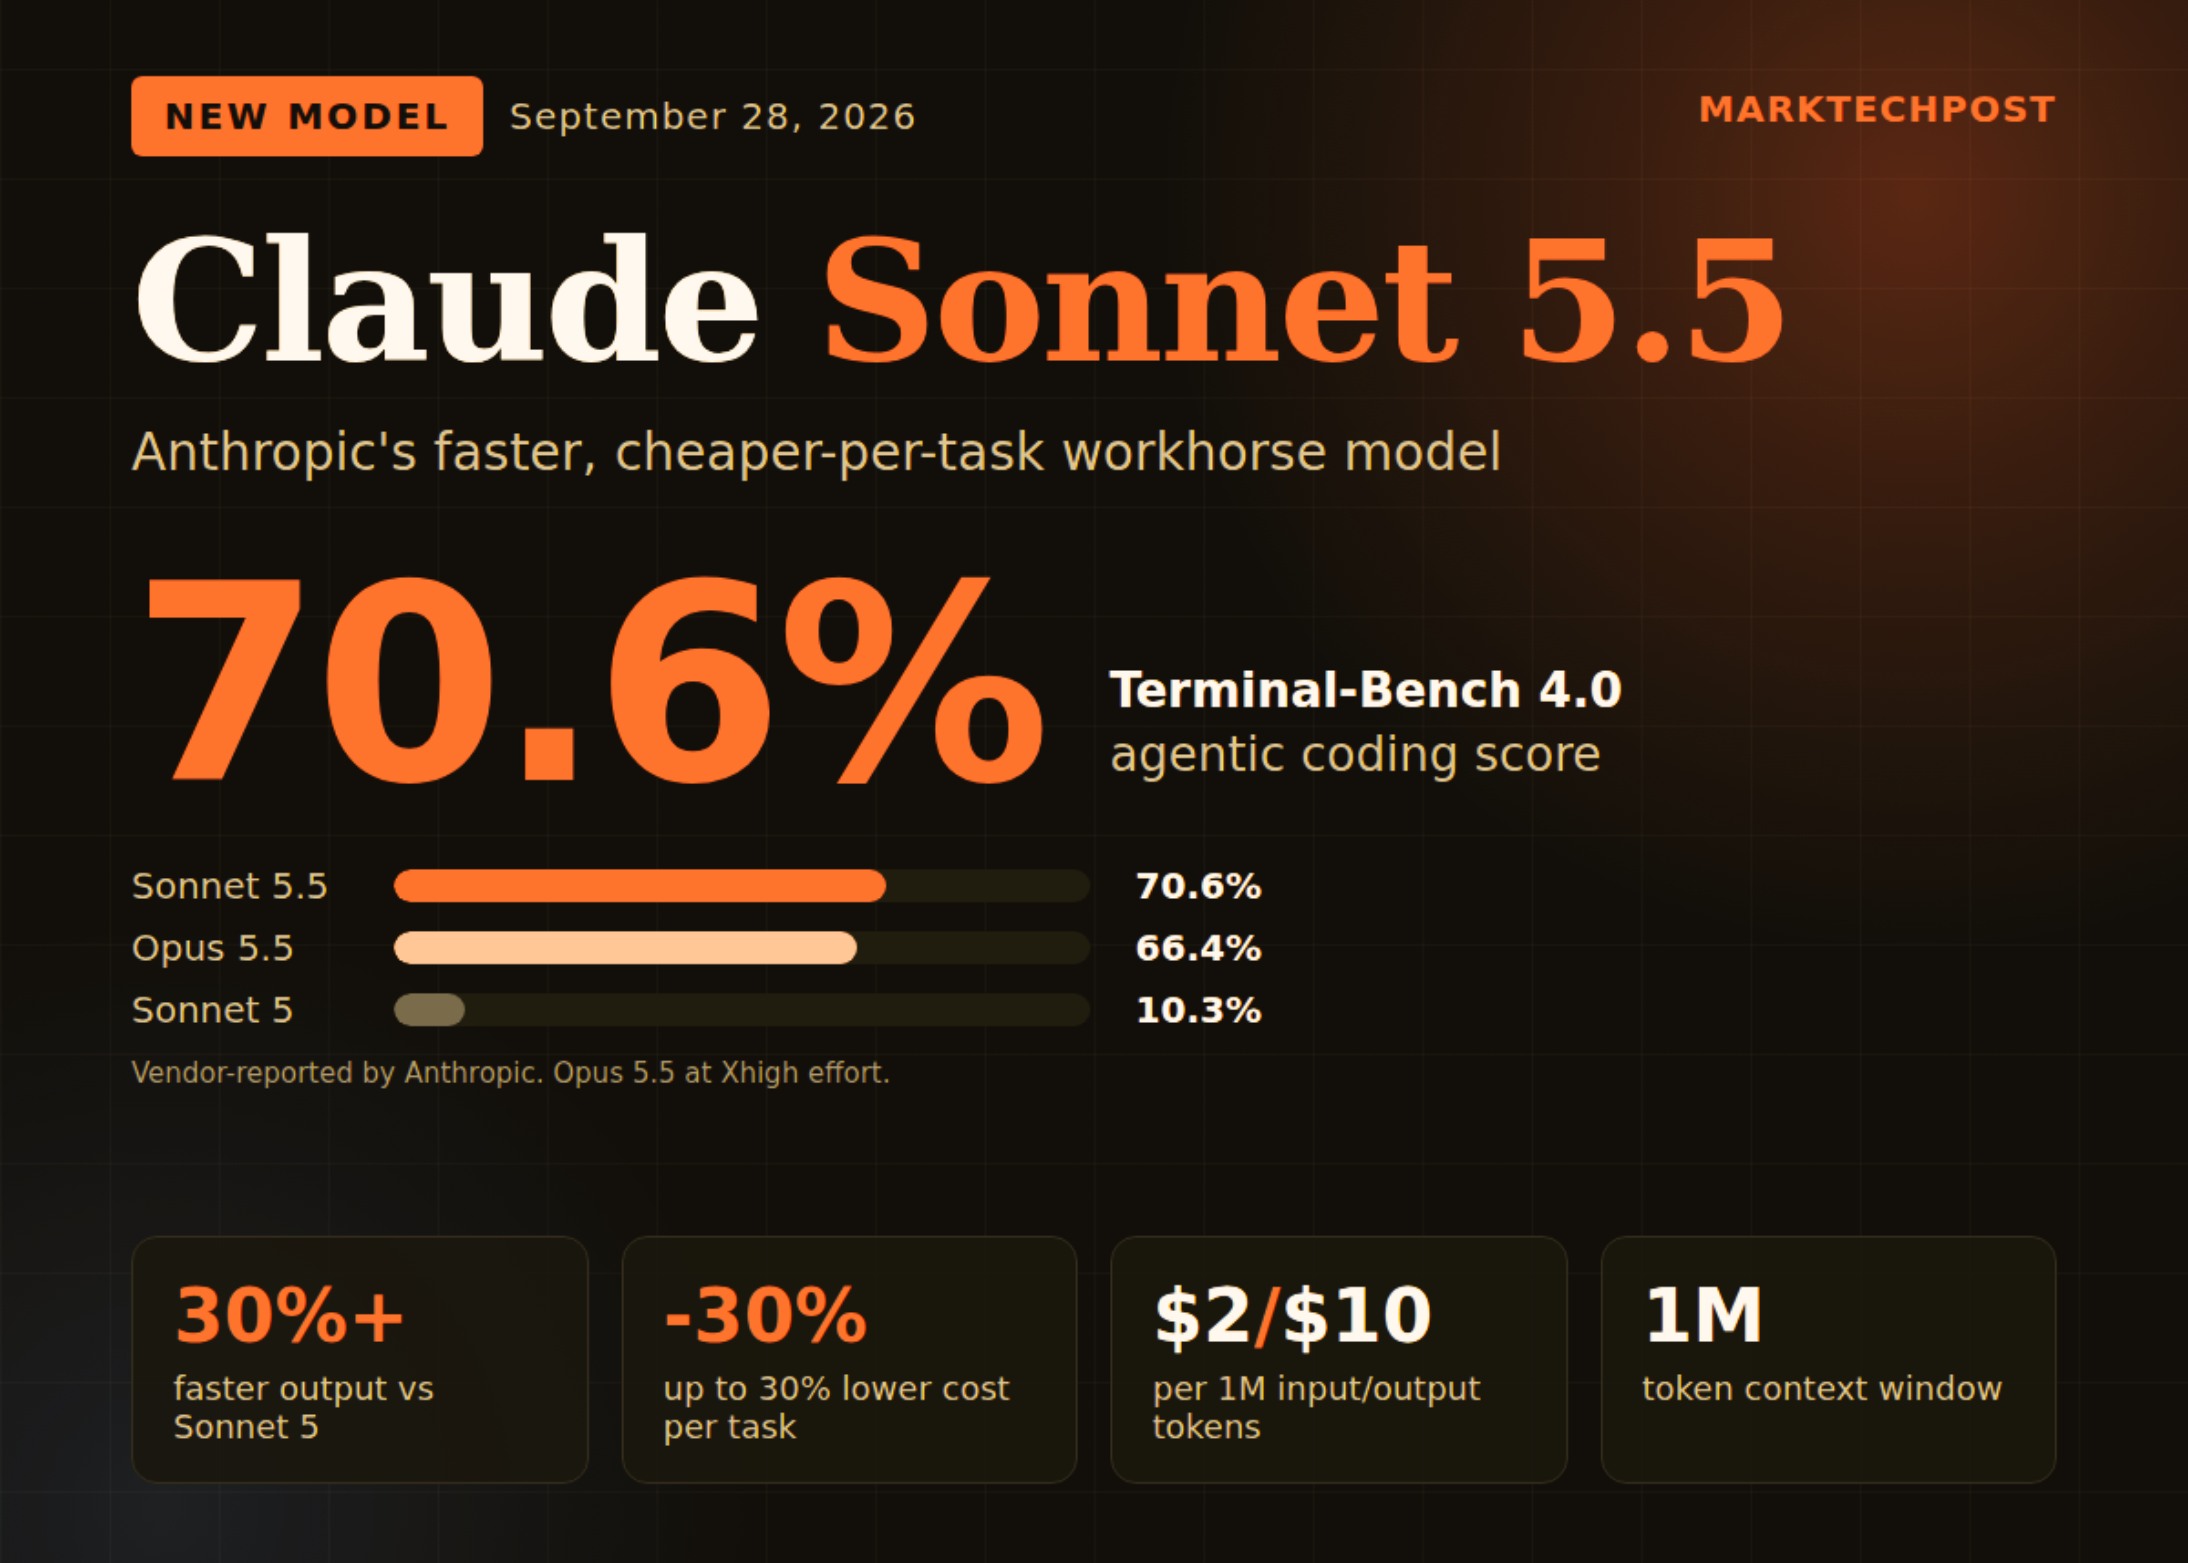
Anthropic just released Claude Sonnet 5.5. It is the second model in the Claude 5.5 family, following Claude Opus 5.5. Anthropic positions it as a faster, lower-cost complement to Opus 5.5. It targets well-scoped everyday tasks, bug fixing, and polished documents, slides, and spreadsheets.
Is it deployable? Yes, It is live on the Claude Platform as claude-sonnet-5-5, plus AWS, Google Cloud, and Microsoft Azure. It is a closed-weights model, so self-hosting is not an option.
What Changed Versus Sonnet 5
Anthropic reports 4 main upgrades over Sonnet 5:
- Speed: output generation is 30%+ faster, making it the fastest Sonnet to date.
- Cost per task: up to 30% lower, because it needs fewer tokens and tool calls.
- Writing: clearer prose, with early testers calling it a better collaboration partner.
- Vision and long-horizon work: it is the first Sonnet to beat Pokémon Red using only screenshots.
Specs from the models overview: 1M-token context, 128K max output, and a June 2026 reliable knowledge cutoff. Adaptive thinking is on by default. Effort runs across 5 levels: low, medium, high, xhigh, and max.
Benchmarks
All scores below are vendor-reported in the launch post. Methodology lives in the Sonnet 5.5 System Card.
- Terminal-Bench 4.0: 70.6%, versus 10.3% for Sonnet 5 and 66.4% for Opus 5.5 at Xhigh.
- CursorBench 4.0: 55.5%, about 2 points below Opus 5.5 (57.8%).
- FrontierCode 1.1: 52.1% at Xhigh and 46.2% at Max. GPT-6 Sol scored 49.3%.
- GDPval-AA v2.1: 1844, versus 1846 for Opus 5.5 and 1449 for Sonnet 5.
- OSWorld 2.1: 80.1% on computer use, close to Opus 5.5 (81.8%).
- Humanity’s Last Exam: 64.5% with tools, up from 54.9%.
The Max result is lower than Xhigh for a reason. At Max, the model more often ran multi-agent code review. That sometimes caused timeouts or out-of-scope edits, which FrontierCode penalizes. Anthropic also states that Opus 5.5 remains clearly stronger on complex, open-ended work.
Pricing and Efficiency
List pricing is unchanged from Sonnet 5: $2 per million input tokens and $10 per million output tokens. Cache reads cost $0.20 and cache writes $2.50 per million. That is half of Opus 5.5 ($4/$20). Savings come from token efficiency, not a price cut.
Customer data supports this. Balyasny Asset Management measured about 121K tokens per answer versus 497K on Sonnet 5. Base44 reported 3.6 iterations per app build, where Opus 5 took 7.7. Zendesk processed tickets 20% faster.
Effort defaults differ by surface. Claude Code and the Claude apps default to Medium. The Claude Platform defaults to High.
How It Compares
| Feature | Claude Sonnet 5.5 | GPT-6 Sol | Gemini 3.1 Pro Preview | Claude Opus 5.5 |
|---|---|---|---|---|
| Developer | Anthropic | OpenAI | Anthropic | |
| Price per 1M tokens (input/output) | $2 / $10 | $2 / $10 (prompts up to 272K) | $2 / $12 (prompts up to 200K) | $4 / $20 |
| Context window | 1M tokens | 1,050,000 tokens | 1,048,576 tokens | 1M tokens |
| Max output | 128K tokens | 128K tokens | 65,536 tokens | 128K tokens |
| Knowledge cutoff | June 2026 | April 20, 2026 | Not listed | June 2026 |
| Reasoning control | Adaptive thinking, 5 effort levels | 6 effort levels (none to max) | Thinking supported | Adaptive thinking (always on) |
| Inputs | Text, image | Text, image | Text, image, video, audio, PDF | Text, image |
| FrontierCode 1.1 | 52.1% (Xhigh) | 49.3% | Not reported | 54.4% |
| GDPval-AA v2.1 | 1844 | 1487 | Not reported | 1846 |
| Chartography (no tools) | 61.6% | 53.6% | Not reported | 64.4% |
| Release stage | Generally available | Generally available | Preview | Generally available |
| Open weights | No | No | No | No |
Benchmark scores are vendor-reported by Anthropic; GDPval-AA runs by Artificial Analysis. Prices are standard API list rates, verified September 28, 2026.
Interactive Explainer
Claude Sonnet 5.5, explained interactively
Tap through benchmarks, effort levels, task cost and the API migration checker.
Meters are illustrative of the direction Anthropic describes (higher effort reasons longer and checks work more). Recommendations come from the Sonnet 5.5 migration guide.
Savings come from fewer tokens and tool calls, not a lower sticker price. Your real ratio depends on workload.
Key Takeaways
- Sonnet 5.5 scores 70.6% on Terminal-Bench 4.0, up from 10.3%.
- Pricing stays $2/$10, but cost per task drops up to 30%.
- It lands within 2 points of Opus 5.5 on GDPval-AA.
- First Sonnet with cyber safeguards and reasoning-extraction classifiers.
- Deployable now via API, AWS, Google Cloud, and Azure.
Check out the official announcement, migration guide, and system card. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
The post Anthropic Releases Claude Sonnet 5.5: 70.6% on Terminal-Bench 4.0 at the Same $2/$10 Price appeared first on MarkTechPost.